Code page 949 (IBM)
IBM code page 949 (IBM-949) is a character encoding which has been used by IBM to represent Korean language text on computers. It is a variable-width encoding which represents the characters from the Wansung code defined by the South Korean standard KS X 1001 in a format compatible with EUC-KR, but adds IBM extensions for additional hanja, additional precomposed Hangul syllables, and user-defined characters.
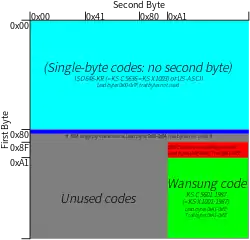 Layout of the IBM-949 code page | |
| Alias(es) |
|
|---|---|
| Language(s) | Korean |
| Created by | IBM |
| Classification | Extended ISO 646, variable-width encoding, CJK encoding |
| Extends | EUC-KR |
| Preceded by | Code page 944 |
Giving values in hexadecimal, bytes 0x00 through 0x7F are used for single byte KS X 1003 (ISO 646:KR) characters, a similar set to ASCII but with a won sign rather than a backslash. Bytes 0x80 through 0x84 are used for IBM single byte extension characters. Lead bytes 0x8F through 0xA0 are used for IBM double byte extension characters. Lead bytes 0xA1 through 0xFE are used for Wansung code (KS X 1001 characters in EUC-KR form, double byte), but with some unused space opened up for user-defined use.
Although both are sometimes named "cp949", IBM-949 is different from Windows code page 949 (IBM-1363), which is Microsoft's Unified Hangul Code, a different extension of EUC-KR. It should also not be confused with IBM's implementation of plain EUC-KR (IBM-970).
Terminology and encoding labelling
Both IBM-949 and Unified Hangul Code (Windows-949) are known as "code page 949" (or "cp949") although they share only the EUC-KR subset in common. Neither has a standardised IANA-registered label to identify it. Although UHC is included in the WHATWG Encoding Standard,[1] with labels including "windows-949",[2] IBM-949 is not. IBM-949 therefore is not permitted in HTML5.
Although the meaning of the label "ibm-949" (and conversely "windows-949" and "ms949") is unambiguous where these labels are supported, the interpretation of the encoding labels "949" and "cp949" consequently varies between implementations. For example, International Components for Unicode uses "cp949", "949", "ibm-949" and "x-IBM949" to refer to IBM-949,[3] and additionally the labels "cp949c", "ibm-949c" and "x-IBM949C" to refer to an variant which uses unmodified ASCII mappings for 0x20–7E (resulting in duplicate mappings for the backslash),[4] while (of the labels incorporating the code page number 949) only "ms949" and "windows-949" are assigned to UHC.[5] This is in contrast to Python, which recognises both "cp949" and "949" (in addition to the more explicit "ms949" and "uhc", but not "windows-949") as labels for UHC, and does not include an IBM-949 codec.[6]
IBM-949 is a variable width encoding defined as the combination of two fixed-width code pages, the single-byte Code page 1088 and the double-byte Code page 951.[7][8][9]
History
A version of Code page 951 (a DBCS-PC, i.e. double-byte non-EUC non-EBCDIC, code), the double-byte component for IBM-949, is defined in the September 1992 revision of IBM Corporate Specification C-H 3-3220-125, along with Code page 834 (a DBCS-Host, i.e. double-byte EBCDIC, code), which is the double byte component of Code page 933.[10] This version of Code page 949/951 considered the entire lead byte range 0x8F–A0 to be a user-defined region, and included only standard Wansung assignments and user-defined areas, thus not including some characters which Code page 933/834 included.[10] Some later versions, such as that implemented by International Components for Unicode (ICU), shrink the user-defined region to include these characters as extensions.[11]
| Language(s) | Korean |
|---|---|
| Extends | N-byte Hangul Code |
| Transforms / Encodes | Code page 933 |
| Succeeded by | IBM code page 949 |
The earlier October 1989 revision of C-H 3-3220-125 had instead defined Code page 926 as its DBCS-PC code, which encoded the same characters as IBM-834 in a layout differing from both IBM-951 and IBM-834, which had a different lead byte range and was not an EUC-KR extension.[10] IBM-926 was combined with Code page 891 or Code page 1040 (respectively 8-bit N-byte Hangul Code and an extension thereof; compare how Shift JIS extends 8-bit JIS X 0201) to form IBM-934 or IBM-944 respectively.[12][13]
Code page 944/926 are now deprecated in favour of IBM-949. The 1992 revision designates code page 926 as "restricted" ("limited to the particular environment for which [it is] registered") and does not give its chart or mappings from the other code pages,[10] and CCSID 944 is categorised as "coexistence and migration"[13] (contrast "interoperable" for CCSID 949).[7] International Components for Unicode includes Unicode mappings for IBM-949[3][11] and IBM-933, but its IBM-944 mapping was removed in 2001.[14]
Single byte codes
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0_ 0 |
NUL 0000 |
┌ 250C |
┐ 2510 |
└ 2514 |
┘ 2518 |
│ 2502 |
─ 2500 |
• 2022 |
◘ 25D8 |
○ 25CB |
◙ 25D9 |
♂ 2642 |
♀ 2640 |
♪ 266A |
♫ 266B |
☼ 263C |
| 1_ 16 |
┼ 253C |
◄ 25C4 |
↕ 2195 |
‼ 203C |
¶ 00B6 |
┴ 2534 |
┬ 252C |
┤ 2524 |
↑ 2191 |
├ 251C |
→ 2192 |
← 2190 |
∟ 221F |
↔ 2194 |
▲ 25B2 |
▼ 25BC |
| 2_ 32 |
SP 0020 |
! 0021 |
" 0022 |
# 0023 |
$ 0024 |
% 0025 |
& 0026 |
' 0027 |
( 0028 |
) 0029 |
* 002A |
+ 002B |
, 002C |
- 002D |
. 002E |
/ 002F |
| 3_ 48 |
0 0030 |
1 0031 |
2 0032 |
3 0033 |
4 0034 |
5 0035 |
6 0036 |
7 0037 |
8 0038 |
9 0039 |
: 003A |
; 003B |
< 003C |
= 003D |
> 003E |
? 003F |
| 4_ 64 |
@ 0040 |
A 0041 |
B 0042 |
C 0043 |
D 0044 |
E 0045 |
F 0046 |
G 0047 |
H 0048 |
I 0049 |
J 004A |
K 004B |
L 004C |
M 004D |
N 004E |
O 004F |
| 5_ 80 |
P 0050 |
Q 0051 |
R 0052 |
S 0053 |
T 0054 |
U 0055 |
V 0056 |
W 0057 |
X 0058 |
Y 0059 |
Z 005A |
[ 005B |
₩ 20A9 |
] 005D |
^ 005E |
_ 005F |
| 6_ 96 |
` 0060 |
a 0061 |
b 0062 |
c 0063 |
d 0064 |
e 0065 |
f 0066 |
g 0067 |
h 0068 |
i 0069 |
j 006A |
k 006B |
l 006C |
m 006D |
n 006E |
o 006F |
| 7_ 112 |
p 0070 |
q 0071 |
r 0072 |
s 0073 |
t 0074 |
u 0075 |
v 0076 |
w 0077 |
x 0078 |
y 0079 |
z 007A |
{ 007B |
| 007C |
} 007D |
~ 007E |
⌂ 2302 |
| 8_ 128 |
¢ 00A2 |
¬ 00AC |
\ 005C |
‾ 203E |
¦ 00A6 |
UDC LEAD | ||||||||||
| 9_ | UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
UDC LEAD |
Hanja/Sym LEAD |
Ext Hanja LEAD |
Ext Hanja LEAD |
Ext Hanja LEAD |
Hanja/Syll LEAD |
Ext Syll LEAD |
| A_ | Ext Syll LEAD |
Punct LEAD 1-_ |
Symbol LEAD 2-_ |
ISO646 LEAD 3-_ |
Jamo LEAD 4-_ |
Greek LEAD 5-_ |
Box LEAD 6-_ |
Units LEAD 7-_ |
Ext Alnum LEAD 8-_ |
Ext Alnum LEAD 9-_ |
Hiragana LEAD 10-_ |
Katakana LEAD 11-_ |
Cyrillic LEAD 12-_ |
13-_ |
14-_ |
15-_ |
| B_ | Syllable LEAD 16-_ |
Syllable LEAD 17-_ |
Syllable LEAD 18-_ |
Syllable LEAD 19-_ |
Syllable LEAD 20-_ |
Syllable LEAD 21-_ |
Syllable LEAD 22-_ |
Syllable LEAD 23-_ |
Syllable LEAD 24-_ |
Syllable LEAD 25-_ |
Syllable LEAD 26-_ |
Syllable LEAD 27-_ |
Syllable LEAD 28-_ |
Syllable LEAD 29-_ |
Syllable LEAD 30-_ |
Syllable LEAD 31-_ |
| C_ | Syllable LEAD 32-_ |
Syllable LEAD 33-_ |
Syllable LEAD 34-_ |
Syllable LEAD 35-_ |
Syllable LEAD 36-_ |
Syllable LEAD 37-_ |
Syllable LEAD 38-_ |
Syllable LEAD 39-_ |
Syllable LEAD 40-_ |
UDC LEAD 41-_ |
Hanja LEAD 42-_ |
Hanja LEAD 43-_ |
Hanja LEAD 44-_ |
Hanja LEAD 45-_ |
Hanja LEAD 46-_ |
Hanja LEAD 47-_ |
| D_ | Hanja LEAD 48-_ |
Hanja LEAD 49-_ |
Hanja LEAD 50-_ |
Hanja LEAD 51-_ |
Hanja LEAD 52-_ |
Hanja LEAD 53-_ |
Hanja LEAD 54-_ |
Hanja LEAD 55-_ |
Hanja LEAD 56-_ |
Hanja LEAD 57-_ |
Hanja LEAD 58-_ |
Hanja LEAD 59-_ |
Hanja LEAD 60-_ |
Hanja LEAD 61-_ |
Hanja LEAD 62-_ |
Hanja LEAD 63-_ |
| E_ | Hanja LEAD 64-_ |
Hanja LEAD 65-_ |
Hanja LEAD 66-_ |
Hanja LEAD 67-_ |
Hanja LEAD 68-_ |
Hanja LEAD 69-_ |
Hanja LEAD 70-_ |
Hanja LEAD 71-_ |
Hanja LEAD 72-_ |
Hanja LEAD 73-_ |
Hanja LEAD 74-_ |
Hanja LEAD 75-_ |
Hanja LEAD 76-_ |
Hanja LEAD 77-_ |
Hanja LEAD 78-_ |
Hanja LEAD 79-_ |
| F_ | Hanja LEAD 80-_ |
Hanja LEAD 81-_ |
Hanja LEAD 82-_ |
Hanja LEAD 83-_ |
Hanja LEAD 84-_ |
Hanja LEAD 85-_ |
Hanja LEAD 86-_ |
Hanja LEAD 87-_ |
Hanja LEAD 88-_ |
Hanja LEAD 89-_ |
Hanja LEAD 90-_ |
Hanja LEAD 91-_ |
Hanja LEAD 92-_ |
Hanja LEAD 93-_ |
UDC LEAD 94-_ |
|
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F |
Letter Number Punctuation Symbol Other Lead byte Undefined Differences from code page 437 (for 0x00–7F) or EUC-KR (for 0x80–FF)
Double byte codes
Lead bytes 0x8F–99, 0xC9, 0xFE (user defined ranges)
IBM-949 is designed to support a maximum of 1880 UDC (user-defined characters),[7] including ranges within unused rows of the Wansung plane, and ranges outside the Wansung plane. In this version, the lead bytes 0x8F–A0 contain a maximum of 1692 UDC, and lead bytes 0xC9 and 0xFE contain a maximum of 94 each (i.e. with trail bytes 0xA0–FE).[10] However, when the extensions to support the entire double-byte repertoire of IBM-933 are implemented, they use lead bytes 0x9A–A0, resulting in a smaller maximum number of characters left for user definition.[3][11]
When mapped to Unicode, 0xC9A1–C9FE (between the syllable and hanja ranges) are mapped to the Unicode Private Use Area code points U+E000–E05D, while 0xFEA1–FEFE (between the end of the hanja range and the end of the plane) are mapped to U+E05E–E0BB. Outside the Wansung plane, 0x8FA0–9AA5 (where the second byte is in the range 0xA1–FE) are mapped to the Private Use Area code points U+E0BC–E4CA.[3] The last of these ranges cuts into the start of the 0x9A row (shown below).
Collectively these private use ranges cover the code points U+E000..E4CA, allowing 1227 UDC to be mapped from IBM-949 to Unicode.[11] The separate private use area range U+F843..F86E is used by IBM to map some characters within the extended hanja range.[11] This follows early recommendations from the Unicode Consortium that corporate characters be allocated from U+F8FF downward and user-defined characters be allocated from U+E000 upward,[17] and is part of a larger corporate private use area scheme which is defined internally by IBM, and includes 192 characters and three unused positions in the range U+F83D..F8FF.[18]
Lead bytes 0x9A–9D (extended symbols and hanja)
0x9AA1 through 0x9AA5 are the end of the user-defined range. The remainder of this range includes some non-Hangul characters included in Code page 933 but not in Wansung code. 0x9AA6 through 0x9AAB contain miscellaneous technical or mathematical symbols. The remainder contains hanja additional to those included in KS X 1001, although some are mapped by IBM to the Private Use Area.
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | PUA E4C6 |
PUA E4C7 |
PUA E4C8 |
PUA E4C9 |
PUA E4CA |
ǂ[lower-alpha 1] 01C2 |
≦ 2266 |
≧ 2267 |
K 212A |
¦ FFE4 |
ʺ 02BA |
喀 F843/5580 |
擱 64F1 |
羯 7FAF |
酣 9163 | |
| B_ | 醵 F844/91B5 |
骼 9ABC |
蒹 84B9 |
哽 54FD |
扃 6243 |
檠 6AA0 |
熲 71B2 |
畊 754A |
稧 F845/7A27 |
雞 96DE |
杲 6772 |
瞽 77BD |
詁 8A41 |
栱 6831 |
槓 69D3 |
箜 7B9C |
| C_ | 蝌 874C |
霍 970D |
盥 76E5 |
鸛 9E1B |
鉸 9278 |
佝 4F5D |
傴 50B4 |
媾 5ABE |
嫗 5AD7 |
晷 F846/6677 |
甌 750C |
覯 89AF |
颶 98B6 |
掬 63AC |
跪 8DEA |
巹 5DF9 |
| D_ | 漌 6F0C |
岌 5C8C |
笈 7B08 |
覇 F847/8987 |
鰭 9C2D |
唜 F848/551C |
糯 7CEF |
喃 5583 |
曩 66E9 |
迺 8FFA |
佞 4F5E |
獰 F849/7370 |
孥 5B65 |
鬧 F84A/9B27 |
靼 977C |
怛 601B |
| E_ | 闥 95E5 |
韃 97C3 |
党 515A |
蟷 87F7 |
碓 7893 |
菟 83DF |
咄 5484 |
垌 578C |
肚 809A |
蚪 86AA |
滕 6ED5 |
灯 706F |
鐙 9419 |
犖 7296 |
幱 5E71 |
埓 57D3 |
| F_ | 榔 6994 |
涼 6DBC |
魎 9B4E |
癘 7658 |
膂 8182 |
蠡 8821 |
鑢 9462 |
櫟 6ADF |
鬣 9B23 |
昤 6624 |
泠 6CE0 |
苓 82D3 |
蛉 86C9 |
潦 6F66 |
艫 826B |
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | 轤 8F64 |
漉 6F09 |
祿 F84B/797F |
轆 8F46 |
籟 7C5F |
蕾 857E |
誄 8A84 |
寥 F84C/5BE5 |
僂 50C2 |
髏 9ACF |
窿 7ABF |
凛 51DB |
廩 5EE9 |
提 F84D/63D0 |
漓 6F13 | |
| B_ | 离 79BB |
螭 87AD |
魑 9B51 |
痳 75F3 |
岦 5CA6 |
媽 5ABD |
蟇 87C7 |
謾 8B3E |
鏝 93DD |
鬘 9B18 |
魍 9B4D |
眛 771B |
苺 82FA |
脉 8109 |
俛 4FDB |
耄 8004 |
| C_ | 鉾 927E |
濛 6FDB |
矇 77C7 |
瀰 7030 |
糜 7CDC |
閩 95A9 |
婆 F84E/5A46 |
欂 6B02 |
牔 7254 |
胖 80D6 |
髣 9AE3 |
魴 9B74 |
潘 F84F/6F58 |
翻 7FFB |
辟 8F9F |
汴 6C74 |
| D_ | 辮 8FAE |
遍 F850/904D |
駢 99E2 |
彆 5F46 |
迸 8FF8 |
鴇 9D07 |
黼 9EFC |
蝠 8760 |
丰 4E30 |
葑 8451 |
仆 4EC6 |
罘 7F58 |
苻 82FB |
蜉 8709 |
頫 982B |
鮒 9B92 |
| E_ | 吟 F851/541F |
蕡 8561 |
巿 F852/5DFF |
髴 9AF4 |
黻 9EFB |
妣 59A3 |
沙 F853/6C99 |
沘 6C98 |
睥 7765 |
篦 7BE6 |
腓 8153 |
轡 8F61 |
髀 9AC0 |
擯 64EF |
蘋 860B |
贇 F854/8D07 |
| F_ | 顰 9870 |
鬢 9B22 |
姒 59D2 |
麝 F855/9E9D |
楂 6942 |
槎 69CE |
笥 7B25 |
槊 69CA |
鑠 9460 |
歃 6B43 |
鍤 9364 |
霎 970E |
殤 6BA4 |
鰓 9C13 |
噬 566C |
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | 婿 5A7F |
齟 F856/9F5F |
射 F857/5C04 |
單 F858/55AE |
尠 5C20 |
愃 6103 |
洗 F859/6D17 |
燹 71F9 |
霰 F85A/9730 |
偰 5070 |
契 F85B/F909 |
挈 6308 |
艘 8258 |
霄 9704 |
蟀 87C0 | |
| B_ | 瑣 7463 |
叟 53DF |
宿 F85C/5BBF |
晬 666C |
溲 6EB2 |
祟 795F |
雎 F85D/96CE |
鶉 9D89 |
虱 8671 |
啻 557B |
寺 F85E/5BFA |
緦 7DE6 |
矧 77E7 |
瑟 F85F/745F |
萼 843C |
贋 8D0B |
| C_ | 鴈 9D08 |
戞 621E |
遏 904F |
嵒 5D52 |
諳 8AF3 |
黯 9EEF |
鞅 9785 |
欸 6B38 |
皚 769A |
礙 7919 |
靉 9749 |
阨 9628 |
射 F860/5C04 |
篛 7BDB |
籥 7C65 |
羘 7F98 |
| D_ | 敔 6554 |
恚 605A |
射 F861/5C04 |
羨 F862/7FA8 |
臙 81D9 |
蠕 8815 |
讌 8B8C |
塩 5869 |
饜 995C |
嬰 5B30 |
睨 7768 |
翳 7FF3 |
蕋 854B |
遨 9068 |
媼 5ABC |
薀 8580 |
| E_ | 鰮 9C2E |
蕘 8558 |
舂 8202 |
蛹 86F9 |
吁 5401 |
熨 71A8 |
蜿 873F |
幃 5E43 |
衞 885E |
囿 56FF |
帷 5E37 |
蕤 8564 |
黝 9EDD |
鬻 9B3B |
檼 6ABC |
珢 73E2 |
| F_ | 齦 9F66 |
挹 6339 |
栮 682E |
頣 9823 |
仞 4EDE |
眥 7725 |
粢 7CA2 |
耔 8014 |
觜 89DC |
赭 8D6D |
柞 67DE |
潜 6F5C |
蚕 8695 |
嶂 5D82 |
瘴 7634 |
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | 装 88C5 |
纔 7E94 |
柢 67E2 |
蛆 86C6 |
豬 8C6C |
糴 7CF4 |
囀 56C0 |
巓 5DD3 |
磚 78DA |
翦 7FE6 |
窃 7A83 |
椄 6904 |
梃 6883 |
晢 6662 |
瑅 7445 | |
| B_ | 踶 8E36 |
吊 F863/540A |
噪 566A |
皁 7681 |
竈 7AC8 |
笊 7B0A |
糶 7CF6 |
絛 7D5B |
鯛 9BDB |
樅 6A05 |
蹤 8E64 |
蔟 851F |
肘 8098 |
隼 96BC |
則 F864/5247 |
証 8A3C |
| C_ | 痣 75E3 |
湌 F865/6E4C |
慚 615A |
刱 5231 |
悵 60B5 |
氅 6C05 |
簀 7C00 |
蜴 8734 |
躑 8E91 |
濺 6FFA |
簷 7C37 |
蜻 873B |
砌 780C |
靆 9746 |
峭 5CED |
綃 7D83 |
| D_ | 鈔 9214 |
鞘 9798 |
數 F866/6578 |
躅 8E85 |
髑 9AD1 |
怱 6031 |
葱 8471 |
摧 6467 |
槌 F867/69CC |
甃 7503 |
箒 7B92 |
鞦 97A6 |
麁 9E81 |
麤 9EA4 |
杻 F868/677B |
舳 8233 |
| E_ | 冲 51B2 |
橇 6A47 |
贅 F869/8D05 |
巵 5DF5 |
徴 5FB4 |
鵄 9D44 |
忱 5FF1 |
拆 62C6 |
橐 6A50 |
駄 99C4 |
幀 F86A/5E40 |
蝙 8759 |
庖 5E96 |
炮 70AE |
舖 8216 |
鉋 924B |
| F_ | 鞄 9784 |
分 F86B/5206 |
蓖 84D6 |
蹕 8E55 |
瘧 7627 |
邯 F86C/90AF |
鷳 9DF3 |
炕 7095 |
廨 5EE8 |
慊 F86D/614A |
篋 7BCB |
陜 F86E/965C |
皞 769E |
醐 9190 |
鶻 9DBB |
Lead bytes 0x9E–A0 (extended hanja and syllables)
0x9EA1 through 0x9EAC contain the remainder of the extended hanja. The rest of the range contains a few additional Hangul syllables which are not available in pre-composed form in pure EUC-KR. Unlike Unified Hangul Code, this is insufficient to support all non-partial Johab syllables absent in Wansung code.
Significant amongst these are 뢔 (rwae, 0x9EFC), 쌰 (ssya, 0x9FE6), 쎼 (ssye, 0x9FED), 쓔 (ssyu, 0x9FF3) and 쬬 (jjyo, 0xA0C1), which correspond to the beginnings of the standard Wansung characters 뢨, 썅, 쏀, 쓩, and 쭁 respectively, when partly entered in an input method editor.
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | 鑊 944A |
圜 571C |
懽 61FD |
鬟 9B1F |
媓 5A93 |
怳 6033 |
囂 56C2 |
猴 7334 |
篌 7BCC |
忻 5FFB |
迄 8FC4 |
頡 9821 |
갂 AC02 |
갋 AC0B |
걹 AC79 | |
| B_ | 겇 AC87 |
겓 AC93 |
곩 ACE9 |
곺 ACFA |
괙 AD19 |
괨 AD28 |
괫 AD2B |
궛 AD9B |
귕 ADD5 |
귬 ADEC |
긂 AE02 |
긏 AE0F |
긑 AE11 |
긧 AE27 |
긼 AE3C |
깄 AE44 |
| C_ | 깉 AE49 |
깢 AE62 |
꺠 AEA0 |
꼄 AF04 |
꼳 AF33 |
꽌 AF4C |
꽘 AF58 |
꽛 AF5B |
꽨 AF68 |
꾓 AF93 |
꾲 AFB2 |
꾿 AFBF |
꿘 AFD8 |
꿧 AFE7 |
뀍 B00D |
뀡 B021 |
| D_ | 끠 B060 |
낐 B090 |
낻 B0BB |
냬 B0EC |
넏 B10F |
넞 B11E |
녇 B147 |
녓 B153 |
녙 B159 |
녯 B16F |
녺 B17A |
놧 B1A7 |
놰 B1B0 |
눳 B233 |
늧 B2A7 |
닁 B2C1 |
| E_ | 닑 B2D1 |
닠 B2E0 |
댱 B331 |
댸 B338 |
덨 B368 |
덪 B36A |
뎜 B39C |
돓 B3D3 |
됀 B400 |
됏 B40F |
됬 B42C |
둗 B457 |
둿 B47F |
뒴 B4B4 |
듁 B4C1 |
듧 B4E7 |
| F_ | 딮 B52E |
딲 B532 |
딷 B537 |
딿 B53F |
땨 B568 |
떄 B584 |
뗴 B5F4 |
뚀 B680 |
뚸 B6B8 |
뜌 B70C |
럐 B7D0 |
렏 B80F |
뢔 B894 |
룜 B8DC |
뤗 B917 |
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | 릐 B990 |
맟 B9DF |
맻 B9FB |
먜 BA1C |
멫 BA6B |
멭 BA6D |
몀 BA80 |
몯 BAAF |
뫃 BAC3 |
뫠 BAE0 |
믁 BBC1 |
믕 BBD5 |
믜 BBDC |
믠 BBE0 |
밎 BC0E | |
| B_ | 밨 BC28 |
밷 BC37 |
뱜 BC5C |
뱨 BC68 |
벘 BC98 |
벜 BC9C |
벹 BCB9 |
볌 BCCC |
볒 BCD2 |
볓 BCD3 |
볔 BCD4 |
봣 BD23 |
붗 BD97 |
붴 BDB4 |
븘 BE18 |
븡 BE21 |
| C_ | 븨 BE28 |
빋 BE4B |
뺜 BE9C |
뺴 BEB4 |
뻭 BEED |
뻰 BEF0 |
뻴 BEF4 |
뻿 BEFF |
뼤 BF24 |
뽜 BF5C |
뽸 BF78 |
뿀 BFC0 |
뿕 BFD5 |
뿝 BFDD |
뿨 BFE8 |
쀄 C004 |
| D_ | 쀠 C020 |
쁙 C059 |
쁴 C074 |
삮 C0AE |
삷 C0B7 |
삻 C0BB |
샃 C0C3 |
샇 C0C7 |
샏 C0CF |
섥 C125 |
섿 C13F |
셑 C151 |
셗 C157 |
솓 C193 |
솻 C1BB |
슌 C28C |
| E_ | 슳 C2B3 |
싀 C2C0 |
싦 C2E6 |
쌂 C302 |
쌋 C30B |
쌧 C327 |
쌰 C330 |
썃 C343 |
썌 C34C |
썻 C37B |
쎅 C385 |
쎙 C399 |
쎠 C3A0 |
쎼 C3BC |
쏼 C3FC |
쐿 C43F |
| F_ | 쑷 C477 |
쒓 C493 |
쓓 C4D3 |
쓔 C4D4 |
씼 C53C |
씿 C53F |
앏 C54F |
앟 C55F |
얐 C590 |
얫 C5AB |
얶 C5B6 |
엱 C5F1 |
엳 C5F3 |
옝 C61D |
옫 C62B |
| _0 | _1 | _2 | _3 | _4 | _5 | _6 | _7 | _8 | _9 | _A | _B | _C | _D | _E | _F | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| A_ | 옺 C63A |
욷 C6B7 |
웟 C6DF |
윋 C70B |
윶 C736 |
읻 C77B |
잧 C7A7 |
잪 C7AA |
젇 C807 |
젔 C814 |
젛 C81B |
젹 C839 |
졋 C84B |
좐 C890 |
좜 C89C | |
| B_ | 좠 C8A0 |
좬 C8AC |
좰 C8B0 |
좸 C8B8 |
죨 C8E8 |
죰 C8F0 |
죱 C8F1 |
줫 C92B |
쥭 C96D |
즤 C9A4 |
짔 C9D4 |
쨰 CA30 |
쩗 CA57 |
쩰 CA70 |
쪗 CA97 |
쪠 CAA0 |
| C_ | 쫒 CAD2 |
쬬 CB2C |
쮀 CB80 |
쯥 CBE5 |
쯰 CBF0 |
찟 CC1F |
찦 CC26 |
찯 CC2F |
찿 CC3F |
챂 CC42 |
챱 CC71 |
챼 CC7C |
쳣 CCE3 |
쳥 CCE5 |
쵀 CD40 |
췃 CDC3 |
| D_ | 츼 CE3C |
칻 CE7B |
캗 CE97 |
캩 CEA9 |
컈 CEC8 |
컽 CEFD |
켙 CF19 |
쾍 CF8D |
쾐 CF90 |
쾟 CF9F |
쾬 CFAC |
쾽 CFBD |
킈 D088 |
턔 D114 |
텠 D160 |
텩 D169 |
| E_ | 퉷 D277 |
튓 D293 |
틍 D2CD |
틧 D2E7 |
팊 D30A |
팦 D326 |
퍙 D359 |
퍠 D360 |
펲 D3B2 |
펵 D3B5 |
폇 D3C7 |
퐤 D424 |
풰 D4B0 |
퓩 D4E9 |
픅 D505 |
픐 D510 |
| F_ | 픙 D519 |
픠 D520 |
픤 D524 |
핟 D55F |
핡 D561 |
핬 D56C |
핱 D571 |
햬 D5AC |
헏 D5CF |
혬 D62C |
횩 D6A9 |
횸 D6B8 |
훕 D6D5 |
휌 D70C |
흭 D76D |
Lead bytes 0xA1–C8, 0xCA–FD (standard Wansung)
See also
Footnotes
- This is not included for IPA support. Rather, in Code page 933, SO 0x4160 is a not-equals sign displayed with a slash, while IBM-933 SO 0x418D is one displayed with a backslash (i.e. =⃥).[10] Although it is IBM-933 SO 0x4160 which is mapped to the usual not-equals GCGID SA540080 (fullwidth of SA540000), it is IBM-933 SO 0x418D which is mapped to EUC-KR and IBM-949 0xA1C1,[10] due to the reference glyph for the not-equals sign in KS C 5601-1987 also showing it with a backslash.[21] Hence, U+2260, which is mapped to EUC-KR and therefore IBM-949 0xA1C1, is mapped to IBM-933 SO 0x418D, leaving IBM-933 SO 0x4160 (and therefore IBM-949 0x9AA6) to be mapped to the visually similar character at U+01C2.[22]
References
- van Kesteren, Anne, "5. Indexes (§ index EUC-KR)", Encoding Standard, WHATWG,
This matches the KS X 1001 standard and the Unified Hangul Code, more commonly known together as Windows Codepage 949.
- van Kesteren, Anne. "4.2. Names and labels". Encoding Standard. WHATWG.
- "Converter Explorer: ibm-949_P110-1999 (alias x-IBM949)", International Components for Unicode, Unicode Consortium
- "Converter Explorer: ibm-949_P11A-1999 (alias x-IBM949C)", International Components for Unicode, Unicode Consortium. This is the ASCII-based version of IBM-949.
- "windows-949-2000", Converter Explorer, International Components for Unicode
- "codecs — Codec registry and base classes § Standard Encodings". Python 3.7.2 documentation. Python Software Foundation.
- "Coded character set identifiers: CCSID 949". IBM Globalization. IBM. Archived from the original on 2014-11-29.
- "CCSID 1088 information document". Archived from the original on 2016-03-26.
- "Code page 951 information document". Archived from the original on 2017-01-16.
- "IBM Korean Graphic Character Set: DBCS-Host and DBCS-PC" (PDF). IBM. 2001 [1992]. C-H 3-3220-125 1992-09.
- International Components for Unicode (ICU), ibm-949_P110-1999.ucm, 2002-12-03
- "Coded character set identifiers: CCSID 934". IBM Globalization. IBM. Archived from the original on 2014-12-02.
- "Coded character set identifiers: CCSID 944". IBM Globalization. IBM. Archived from the original on 2014-12-01.
- Viswanadha, Ram (2001-11-01). "ICU-1281 Remove unwanted ucmfiles". International Components for Unicode.
- Code Page CPGID 01088 (pdf) (PDF), IBM
- Code Page CPGID 01088 (txt), IBM
- "2.0: Changes in Unicode 1.0" (PDF). The Unicode Standard, Version 1.1. Unicode Consortium. pp. 3–4. UTR #4.
- "CPGID 01449: IBM default PUA". IBM Globalization: Code page identifiers. IBM. Archived from the original on 2015-09-16.
IBM has designated 195 positions from U+F83D to U+F8FF for use as IBM Corporate-zone and intends to use them consistently within IBM whenever there is a need to maintain the round-trip integrity of IBM characters. […] At present CS 3099 containing 192 IBM Corportate [sic] characters has been defined.
- "ibm-933_P110-1995.ucm". International Components for Unicode.
- Private Use Area mapped hanja are identified from code charts. The IBM document C-H 3-3220-125 1992-09 gives code charts for the code pages used as the double-byte components for Code page 933 and an older version of Code page 949 without these extensions; however, the hanja in this section correspond to (and are in the same order as) the subset of table 7 for which a "PC Code" is not listed.[10] The Corporate Private Use Area mappings are also co-ordinated with other code pages,[18] including Code page 933,[19] which can be used to obtain the "Host Code" for a given Corporate Private Use Area mapping.
- Korea Bureau of Standards (1988-10-01). Korean Graphic Character Set for Information Interchange (PDF). ITSCJ/IPSJ. ISO-IR-149.
- "ibm-933_P110-1995 (lead bytes 0E41)". Converter Explorer. International Components for Unicode.
